WebOperator
WebOperator: Action-Aware Tree Search for Autonomous Agents in Web Environment
🌐 Website • 📃 Paper • 💻 Code • 🗂️ Trajectories • 🧪 WebReplayBench

📖 Abstract
LLM-based agents often operate in a greedy, step-by-step manner, selecting actions solely based on the current observation without considering long-term consequences or alternative paths. This lack of foresight is particularly problematic in web environments, which are only partially observable—limited to browser-visible content (e.g., DOM and UI elements)—where a single misstep often requires complex and brittle navigation to undo. Without an explicit backtracking mechanism, agents struggle to correct errors or systematically explore alternative paths. Tree-search methods provide a principled framework for such structured exploration, but applying them to the web introduces two challenges: replaying an action sequence may not reconstruct the same page, and some actions may irreversibly change the website. To address these challenges, we introduce WebOperator, a tree-search framework that enables validated backtracking and strategic exploration. Our method incorporates a best-first search strategy that ranks actions by both reward and reversibility, along with a robust backtracking mechanism that verifies reconstructed pages before continuing from them. It prioritizes reversible actions, postpones potentially irreversible ones, and discards earlier branches when its post-execution heuristic flags a possible persistent change. Experiments on WebArena and WebVoyager demonstrate the effectiveness of the framework. On WebArena, it achieves 54.6% task success with gpt-4o, outperforming all prior tree-search methods using the same backbone. Controlled ablations show that naive tree search can reduce performance, whereas action-aware selection and validated backtracking improve corrective search. We further introduce WebReplayBench, a web environment that records which actions actually change the website’s state, to evaluate whether WebOperator detects irreversible actions and avoids repeating them during backtracking.
📊 Results on WebArena Benchmark
| Agent | Model | Overall (#812) | Reddit (#106) | GitLab (#180) | Shopping (#187) | CMS (#182) | Map (#109) | Multisite (#48) |
|---|---|---|---|---|---|---|---|---|
| BrowserGym | gpt-4 | 15.0 | 20.2 | 19.0 | 17.2 | 14.8 | 25.5 | - |
| LM-TS | gpt-4o | 19.2 | 11.3 | 13.9 | 27.8 | 16.5 | 26.6 | 16.7 |
| Go-Browse | qwen-2.5-7b | 22.6 | 30.7 | 15.3 | 22.4 | 25.3 | 17.9 | - |
| AWM | gpt-4 | 35.5 | 50.9 | 31.8 | 30.8 | 29.1 | 43.3 | - |
| Branch-n-Browse | gpt-4o | 35.8 | 50.9 | 36.7 | 34.6 | 26.4 | 46.8 | 18.8 |
| WebPilot | gpt-4o | 37.2 | 65.1 | 39.4 | 36.9 | 24.7 | 33.9 | - |
| AgentOccam | gpt-4-turbo | 45.7 | 67.0 | 43.3 | 46.2 | 38.9 | 52.3 | 16.7 |
| AgentSymbiotic | claude-3.5 | 52.1 | 66.0 | 51.0 | 48.0 | 49.0 | 60.0 | 29.0 |
| ScribeAgent | gpt-4o | 53.0 | 73.7 | 59.7 | 45.8 | 37.9 | 56.3 | - |
| WebOperator | gpt-4o | 54.56 | 76.42 | 52.78 | 49.20 | 54.95 | 55.05 | 31.25 |
Experimental trajectories: run logs, search trees and step-by-step viewers for every task.
- WebArena (812 tasks): Hugging Face · GitHub · viewer, e.g. task 421
- WebArena-lite ablations (155 tasks, one run per ablation row, with scripts that recompute the tables): Hugging Face
📂 Project Structure
.
├── weboperator/                 # Source code for the web agent
│   └── configs/                 # Agent configurations (demo, WebArena, WebVoyager)
├── webshepherd/                 # Source code for the Process Reward Model
├── browsergym/                  # Source code for the web environment simulator
├── gobrowse/                    # Source code for the experience retrieval module
├── webarena/, webvoyager/       # Benchmark task files and evaluation code
├── webreplaybench_eval/         # Harness that runs WebOperator on WebReplayBench
├── utils/                       # Scripts that collect runs and compute benchmark scores
├── run.py, demo.py              # Entry points
└── README.md

# The project page lives on the gh-pages branch.
⚙️ Installation
1️⃣ Clone the repository
git clone https://github.com/kagnlp/WebOperator.git
cd WebOperator
2️⃣ Create environment
conda create -n weboperator_env python=3.12
conda activate weboperator_env
# or using pip and virtualenv (if python3.12 is the system python)
python -m venv weboperator_env
source weboperator_env/bin/activate  # On Windows use `weboperator_env\Scripts\activate`
3️⃣ Install dependencies
Refer to the Running with Docker section if you don’t have admin rights to install Playwright dependencies.
pip install -r requirements.txt
playwright install chromium --with-deps # Need admin rights
4️⃣ Set up environment variables
Create a .env file by copying the example configuration:
cp .env.example .env
Then open the .env file and update any necessary values (such as API keys, website urls) according to your environment.
🚀 Usage
Run the Demo
python demo.py
or
python run.py --config weboperator/configs/demo.yml
🐳 Running with Docker
Useful if you don’t have admin rights to install Playwright dependencies. No need to create a virtual environment or install dependencies.
docker compose run --user $(id -u) weboperator --config weboperator/configs/demo.yml
Skeleton Code
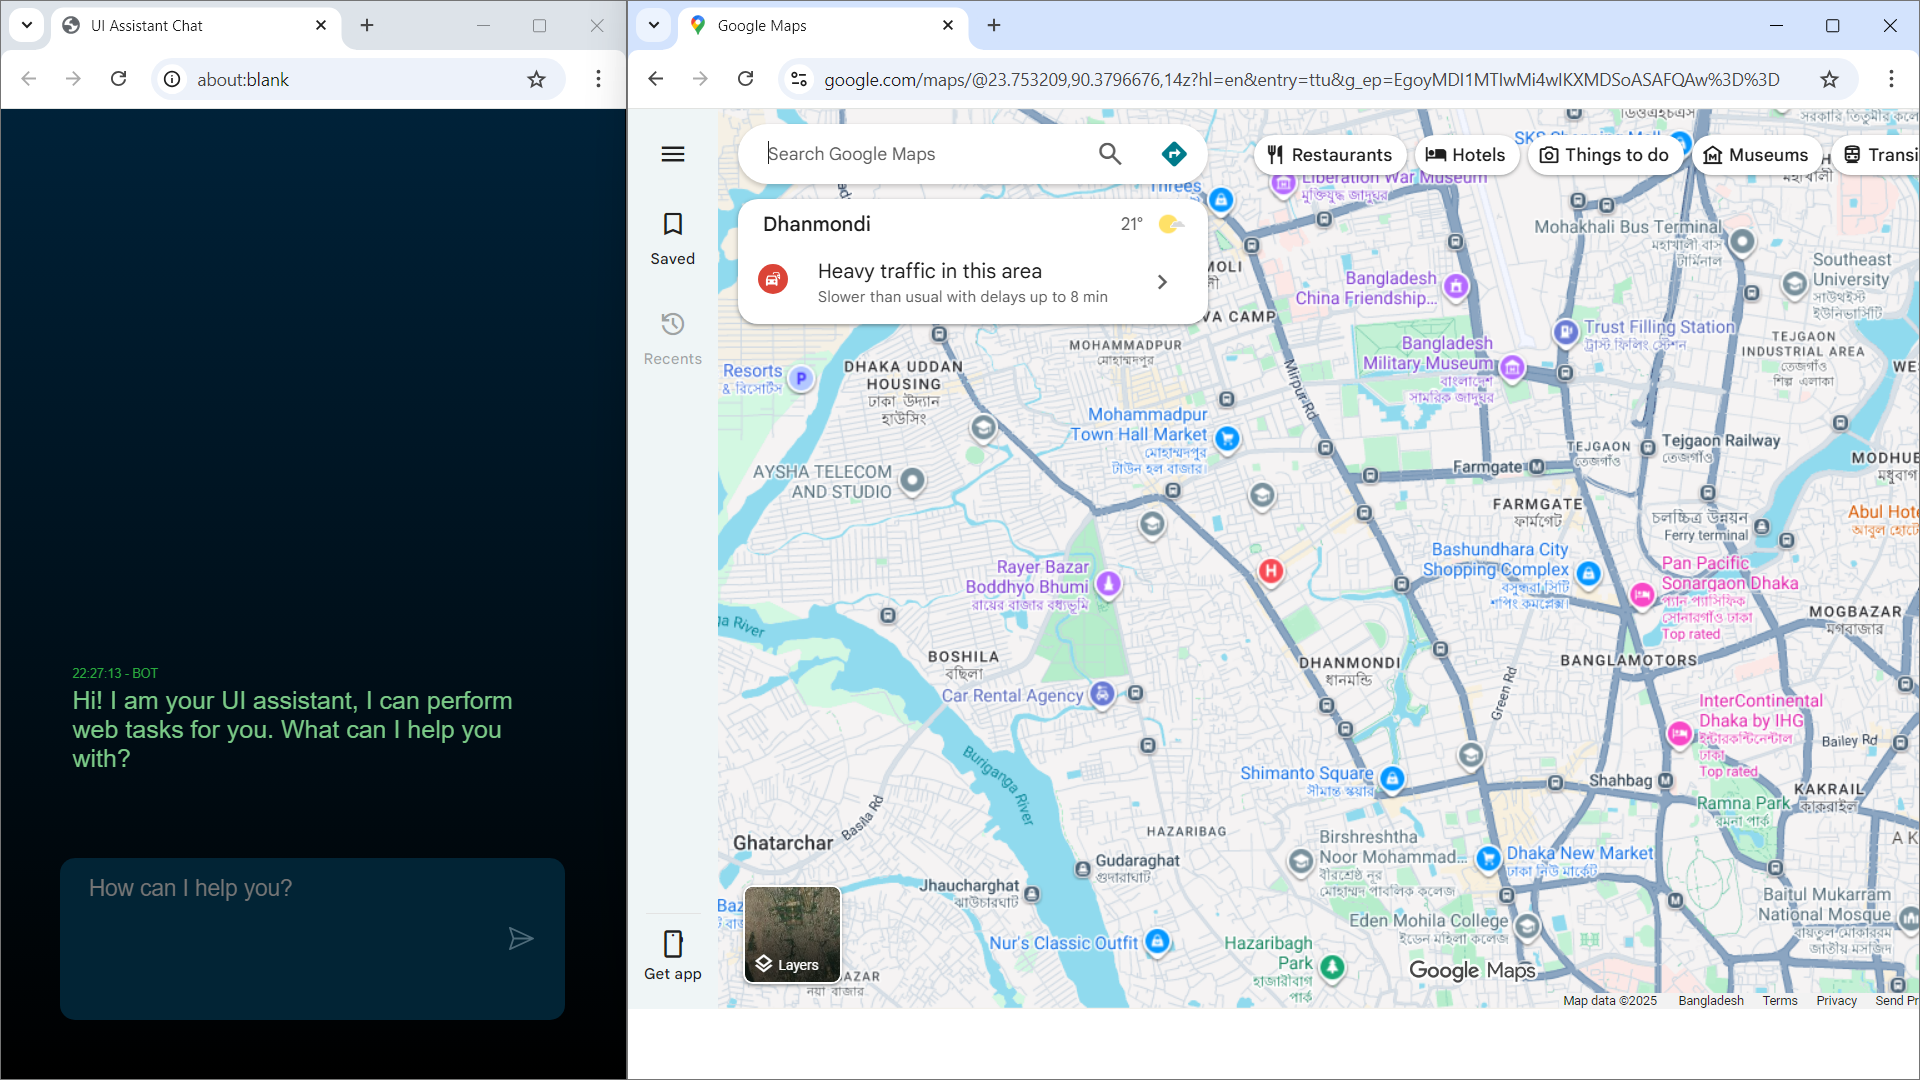
Boilerplate code (demo.py) to run WebOperator on an interactive, open-ended task:
import gymnasium as gym
import browsergym.core  # register the openended task as a gym environment
from weboperator.tree_search_agent import TreeSearchAgent
from weboperator.action_generator import ActionGenerator
from weboperator.models.openrouter import OpenRouterModel

# start an openended environment
env = gym.make(
    "browsergym/openended",
    task_kwargs={"start_url": "https://map.google.com/"},  # starting URL
    wait_for_user_message=True,  # wait for a user message after each agent message sent to the chat
    headless=False
)

# Create an agent
action_generator = ActionGenerator(
    model=OpenRouterModel("openai/gpt-oss-20b:free")  # Set OPENROUTER_API_KEYS in .env file
)
agent = TreeSearchAgent(
        chat_mode=True,
        action_generator= action_generator,
    )

# run the environment <> agent loop until termination
obs, info = env.reset()
while True:
    preprocessed_obs = agent.obs_preprocessor(obs) # Preprocess observation
    action = agent.get_action(preprocessed_obs, env) # Decide action
    obs, reward, terminated, truncated, info = env.step(action) # Act and Observe
    if terminated or truncated:
        break
# release the environment
env.close()
Sample Output
Open-ended + Google Maps
🎯 Benchmarks
WebArena Setup
Before running WebArena experiments, you must host the WebArena websites and configure the corresponding endpoints.
Host Websites (choose one):
- Official setup: https://github.com/web-arena-x/webarena/blob/main/environment_docker/README.md
- Unofficial (simplified): https://github.com/mahirlabibdihan/webarena-docker
Set Environment Variables:
PUBLIC_HOSTNAME=<YOUR_SERVER_DOMAIN_OR_IP>

export WA_SHOPPING=http://${PUBLIC_HOSTNAME}:7770
export WA_SHOPPING_ADMIN=http://${PUBLIC_HOSTNAME}:7780/admin
export WA_REDDIT=http://${PUBLIC_HOSTNAME}:9999
export WA_GITLAB=http://${PUBLIC_HOSTNAME}:8023
export WA_GITLAB_IP=${PUBLIC_HOSTNAME}
export WA_WIKIPEDIA=http://${PUBLIC_HOSTNAME}:8888/wikipedia_en_all_maxi_2022-05/A/User:The_other_Kiwix_guy/Landing
export WA_MAP=http://${PUBLIC_HOSTNAME}:3000
Inference
Run the agent on each benchmark using the corresponding configuration file.
-
WebArena
python run.py --config weboperator/configs/wa-gpt-4o.yml -
WebVoyager
python run.py --config weboperator/configs/wv-gpt-4o.yml
Evaluation
Move the inference outputs and compute benchmark scores.
-
WebArena
python -m utils.move_exp --src_dir results/webarena/gpt-4o --dst_dir experiments/webarena/gpt-4o python -m utils.eval_exp --results_dir experiments/webarena/gpt-4o --task_type webarena -
WebVoyager
python -m utils.move_exp --src_dir results/webvoyager/gpt-4o --dst_dir experiments/webvoyager/gpt-4o
python -m utils.eval_exp --results_dir experiments/webvoyager/gpt-4o --task_type webvoyager
WebReplayBench
WebReplayBench is a separate benchmark: a website whose database records every
persistent change, with backtracking scenarios as a JSON dataset. The harness in
webreplaybench_eval/ runs WebOperator on it, to
measure how often backtracking replays destructive actions, from naive replay up to
full WebOperator. With WebReplayBench cloned next to this repository, on a Docker host:
bash webreplaybench_eval/run_ladder.sh 8
⚙️ Agent Configuration Explanation
Environment
env:
  task_type: "openended" # ["webarena", "webvoyager", "openended"]
  max_steps: 100 # Maximum steps per episode (For BrowserGym)
  headless: false # false: show browser UI; true: hide browser UI
Experiment
experiment:
  results_dir: "./results/openended/gpt-oss-20b" # Directory to save results. Give relative path.
Agent
agent:
  allow_unauthorized_page: true # Whether allow visit to pages outside the benchmark domain
Models
models: # List of models used in the agent
  action_model: # Unique identifier of the model
    type: "OpenRouterModel" # Options: ["OpenAIModel", "AzureOpenAIModel", "OpenRouterModel", "OpenHFModel"]
    model_name: "openai/gpt-oss-20b:free"
  reward_model:
    type: "AzureOpenAIModel"
    model_name: "gpt-4o"
    temperature: 1.0
Agent Components
components:
  action_validator: # Optional: Action validator configuration
    allow_invalid_action: false # Whether to allow semantically invalid actions (Default: false)
    allow_invalid_page: false # Whether to allow navigation to invalid pages (Default: false)

  observation_processor: # Observation processor configuration
    optimized: true # true: use full or visible-only observation based on the observation size. false: always use visible-only observation
    truncate_error_message: true # Truncate long error messages

  action_processor: # Action processor configuration
    merge_strategy: "sum" # ["sum", "max", "none"]: strategy to merge semantically similar actions. "none": do not merge.

  recovery_assistant: # Optional: Recovery assistant configuration
    recover_from_invalid_page: true # true: forcefully go_back or tab_close when on invalid page
    recover_from_captcha: true # Whether to allow human intervention for captcha recovery

  backtrack_manager: # Optional: Enables backtracking mechanism
    destruction_aware: true # Whether to re-root the tree after executing destructive actions
    simulation_verified: true # Whether to do snapshot-validation or not

  action_selector: # Action selection strategy configuration
    selection_strategy: "action-aware" # options: ["highest-reward", "action-aware"]
    search_budget: 4 # Frontier budget
    n_candidates: 2 # Number of solution candidates to consider
    max_depth: 20 # Maximum search depth
    max_steps: 20 # Maximum steps (excluding backtracking steps)

  rephraser: # Optional: Enables instruction rephraser
    model: "action_model" # Model used for rephrasing instructions

  retriever: # Optional: Enables examples retriever (Set RETRIEVER_API_SERVER in environment variables)
    type: "faiss" # ["faiss", "bm25"]
    model: "all-MiniLM-L6-v2" # Sentence transformer model (for faiss retriever)
    top_k: 5 # Number of examples to retrieve

  judge: # Reward and checklist model configuration. Note: Applicable only for multiple action candidates
    prompt_type: "web_operator"  # Options: likert_scale, web_shepherd, web_operator
    checklist_model: "reward_model" # Model used for checklist generation
    reward_model: "reward_model" # Model used for reward estimation

  action_generator:
    max_retry: 5 # Maximum retries for generating syntactically and semantically valid actions
    full_action_space: # List of all possible actions
      - "click"
      - "fill"
      - "select_option"
      - "goto"
      - "go_back"
      - "go_forward"
      - "scroll"
      - "new_tab"
      - "tab_focus"
      - "tab_close"
      - "stop"
    action_space_type: "adaptive" # options: ["fixed", "adaptive"]
    candidates: # List of action generator candidates
      - name: "simple_action_generator" # Unique name for the candidate
        model: "action_model" # Model to use
        history_length: 5 # Number of previous steps to include in the context
        rephraser: false # Whether to include rephrased task instruction
        retriever: false # Whether to include retrieved examples
      - name: "action_generator_w_retriever"
        model: "action_model"
        history_length: 3
        rephraser: false
        retriever: true
      - name: "action_generator_w_rephraser"
        model: "action_model"
        history_length: 4
        rephraser: true
        retriever: false
📝 Citation
Please cite our paper:
@article{dihan2025weboperator,
  title={WebOperator: Action-Aware Tree Search for Autonomous Agents in Web Environment},
  author={Dihan, Mahir Labib and Hashem, Tanzima and Ali, Mohammed Eunus and Parvez, Md Rizwan},
  journal={arXiv preprint arXiv:2512.12692},
  year={2025}
}